Estimate — sign in for exact rates.

 Trusted GPU & AI infrastructure since 2015 — Huntsville, AL
20 GB GDDR6 · RDNA 3 · gfx1100

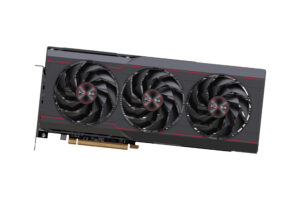
AMD Radeon RX 7900 XT 20GB

The RX 7900 XT has 20 GB of GDDR6 memory. Its proposed Qwen3.8-27B UD-IQ4_XS recipe uses a compact conversion and 16K catalog context, distinct from the XTX’s Q4 32K candidate. The practical question is whether the exact file, context and desktop memory load produce useful answers and latency on this card; the nominal weight size cannot settle that.

For two XTs, a Q8 model split across cards is a capacity experiment, while two IQ4 workers would handle independent jobs. A pair needs slot, negotiated PCIe-link, power and cooling checks. Bitworks has not yet qualified either exact recipe or published its own fit or speed measurements; external reports below use other configurations. Flash-Next remains a separate host-offload research path.

AMD specifications

Recipes

Windows

Linux

Community reports — not measured or reproduced by Bitworks

Reported by others, linked to the original. Bitworks has not verified these numbers; they can differ on your system.

Reported on GitHub by sterlp — posted 2026-09-11 Original report

Not reproduced by Bitworks

Dual RX 7900 XT Windows stream-stall issue

Method (as reported): Reporter describes one stalled streaming request and uncertain server/client cause; in-flight slot rate is not completed throughput.

  • Reported GPU setup 2 × RX 7900 XT
  • GPU count 2
  • Operating system Windows (native Windows x86-64)
  • Engine llama.cpp 0.4.0-dev build 10817; Clang 20.1.8
  • Backend Vulkan
  • Model Qwen3.8-27B Unsloth UD-Q5_K_XL (Unsloth)
  • Configured context 150,000 tokens
  • Actual input input length not reported
  • Full window tested no
  • Reported context Issue does not establish achieved prompt occupancy or completed work.
  • Topology not reported — Actual device split and active client count unreported.
  • Speculative decoding draft MTP max 4
  • CPU Ryzen 7 7800X3D

Not reported: model file checksum, topology, system memory, driver version, exact GPU device selection/split and residency, number of simultaneous clients and active slots, whether the server or client caused the stalled stream, completed request performance

  • Closed issue remains labeled bug-unconfirmed; the reporter was not certain the server caused the stall.
  • The server alias says Qwen3.6, but the model path is Qwen3.8; do not use the alias as model identity.
  • No numeric dual-GPU performance recommendation can be derived.
Setup guide (external)

Reported on GitHub by Akciali — posted 2026-08-14 Original report

Not reproduced by Bitworks

llmfit single RX 7900 XT Qwen3.8 submission

Method (as reported): llmfit bench --provider llamacpp; three separate forced-300-output runs; reported mean total duration 9.73093 s.

HEAD seen at retrieval: 9f1c5aebe76b (not necessarily the commit the author measured)

  • Reported GPU setup RX 7900 XT 20GB
  • GPU count 1
  • Operating system Linux (Linux distribution unreported)
  • Engine llama.cpp via llmfit llmfit 1.1.9; llama.cpp build unreported
  • Backend RADV/Vulkan
  • Model Qwen3.8-27B Unsloth Q4_K_M (Unsloth)
  • Configured context 4,096 tokens
  • Actual input input length not reported
  • Output 300 tokens
  • Full window tested no
  • Reported context Prompt occupancy unreported; 300 output tokens forced by ignore-eos.
  • Simultaneous clients 1
  • Topology single (Host has two same cards; submission says one used exclusively.)
  • CPU Intel Core i9-10900X
  • Memory configuration 62.49 GB reported by llmfit
  • 30.83 tok/s ± 0.39 (as reported, n = 3) — other (scope not stated) · Synthetic benchmark (not API serving) · 1 client
    Mean of three 300-output runs; min 30.67, max 31.06; average total duration 9.73093 s; timing phase unspecified.
    This row: configured context: 4,096 tokens · quantisation: Unsloth Q4_K_M

Not reported: system memory, llama.cpp build and driver version, exact model SHA-256 value, though submitter states Hub digest was checked, actual prompt-token occupancy, whether recorded throughput excludes prompt processing, concurrent-request behavior

  • Linux single-card result, not native Windows or dual-card scaling.
  • The JSON's memTierGb=16 conflicts with vramGb=19.98 and the named 20GB RX 7900 XT; do not convert that tier into a card specification.

Setup guide (external)

Related link (external)

Reported on GitHub by Niko1221 / Strata maintainers Original report

Not reproduced by Bitworks Project documentation — capability, not a measurement

Strata AMD HIP guide

Method (as reported): Maintainer documents Windows bundled HIP runtime, per-card checks and Linux layer split; no discrete AMD Windows model-load validation.

HEAD seen at retrieval: 6f32ec070f23 (not necessarily the commit the author measured)

  • Reported GPU setup Windows: one GPU per model; Linux: selectable layer split
  • GPU count not reported
  • Operating system Windows and Linux (Windows HIP and Linux HIP)
  • Engine Strata HIP
  • Backend HIP
  • Model Qwen3.8-Flash-Next pack
  • Actual input input length not reported
  • Topology not reported — Windows one GPU per model; Linux selectable layer split

Not reported: model quantisation, configured context, actual input length, simultaneous clients, topology, CPU, system memory, release archive digest and revision, Windows discrete-card load, Windows dual-card execution, quality and memory curves

  • Maintainer says ready-made Windows archive has not run a model on a discrete AMD card in documented validation.
  • Capability documentation, not a measured compatibility or performance result.
  • RX 9060 XT memory variant is unspecified in the guide, so neither variant is mapped.

Setup guide (external)

Related reports from the same author or project — not independent replication

Reported on GitHub by cadamcat Original report

Not reproduced by Bitworks

Dual Radeon vLLM: llama.cpp layer-split comparison

Method (as reported): Two-card llama-bench depth sweep, tg128, layer split; ROCm and Vulkan.

HEAD seen at retrieval: 60c702076233 (not necessarily the commit the author measured)

  • Reported GPU setup 2 × RX 7900 XT 20GB
  • GPU count 2
  • Operating system Linux (Proxmox VFIO Linux guest)
  • Environment VM guest
  • Engine llama.cpp 47c786924
  • Backend ROCm and Vulkan
  • Model Qwen3.6-27B Q4_K_M
  • Actual input input length not reported
  • Output 128 tokens
  • Reported context Author swept recorded prompt depths from 512 to 32768.
  • Simultaneous clients 1
  • Workers 1
  • Topology dual-split (Two cards, layer split, no P2P, VFIO guest)
  • CPU Threadripper 1950X
  • Board X399
  • PCIe cross-die PCIe 3.0
  • 28.61 tok/s — generation speed (per request) · Synthetic benchmark (not API serving) · 1 client · input 512 tokens
    Compared with 24.89 tok/s (Vulkan versus ROCm at 512-token depth); reported difference: other
    llama-bench tg128; Vulkan reported, ROCm baseline
  • 26.04 tok/s — generation speed (per request) · Synthetic benchmark (not API serving) · 1 client · input 32,768 tokens
    Compared with 21.84 tok/s (Vulkan versus ROCm at 32768-token depth); reported difference: other
    llama-bench tg128; Vulkan reported, ROCm baseline

Not reported: configured context, system memory, Exact GGUF digest, Repetition count and variance, Native Windows result, Concurrent API behavior

  • Qwen3.6 is not Qwen3.8.
  • Linux VFIO without P2P does not establish bare-metal or native Windows speed.
  • Synthetic decode is not concurrent API throughput.

Setup guide (external)

Reported on GitHub by cadamcat · measured 2026-08-24 Original report

Not reproduced by Bitworks

Dual Radeon vLLM: Qwen3.8 checkpoint campaign

Method (as reported): Random-prefix request ladder; decode first token to last; one stack per campaign.

HEAD seen at retrieval: 60c702076233 (not necessarily the commit the author measured)

  • Reported GPU setup 2 × RX 7900 XT 20GB
  • GPU count 2
  • Operating system Linux (Proxmox VFIO Linux guest)
  • Environment VM guest
  • Engine vLLM 0.23 patched container
  • Backend ROCm
  • Model Qwen3.8-27B asymmetric AWQ int4 checkpoint
  • Actual input input length not reported
  • Reported context Author reports depth ladder with random prefixes, without a configured-context claim.
  • Simultaneous clients 1
  • Workers 1
  • Topology dual-split (Tensor parallel, no P2P, VFIO guest)
  • CPU Threadripper 1950X
  • Board X399
  • PCIe cross-die PCIe 3.0
  • 12.3 tok/s — generation speed (per request) · API server · 1 client
    First-to-last decode at roughly 500-token depth; TTFT excluded
  • 10.7 tok/s — generation speed (per request) · API server · 1 client
    First-to-last decode at roughly 32000-token depth; TTFT excluded

Not reported: system memory, Checkpoint digest, Exact configured context, Per-row variance, Native Windows result, Concurrent-client throughput

  • This asymmetric checkpoint missed the native gfx1100 W4A16 kernel.
  • Later vLLM and attention-patch results are separate software stacks.
  • Same author and host as related dual-XT rows; not an independent replication.

Setup guide (external)

Reported on GitHub by cadamcat Original report

Not reproduced by Bitworks

Dual Radeon: controlled Qwen3.8 split-KV attention test

Method (as reported): Two reverse-order A/B passes; fresh container per cell; same checkpoint; attention file only changed.

HEAD seen at retrieval: 60c702076233 (not necessarily the commit the author measured)

  • Reported GPU setup 2 × RX 7900 XT 20GB
  • GPU count 2
  • Operating system Linux (Proxmox VFIO Linux guest)
  • Environment VM guest
  • Engine vLLM 0.27.1.dev
  • Backend ROCm 10.0
  • Model Qwen3.8-27B same asymmetric AWQ int4 checkpoint
  • Actual input input length not reported
  • Reported context Approximate reported depth rungs; exact occupied inputs not established here.
  • Simultaneous clients 1
  • Workers 1
  • Topology dual-split (Tensor parallel, no P2P, VFIO guest)
  • CPU Threadripper 1950X
  • Board X399
  • PCIe cross-die PCIe 3.0
  • 35.2 tok/s — generation speed (per request) · API server · 1 client
    Compared with 3.83 tok/s (split-KV PR versus stock, first pass); reported difference: engine build
    First pass at reported 32768-token depth; same checkpoint and harness
  • 37.05 tok/s — generation speed (per request) · API server · 1 client
    Compared with 3.81 tok/s (split-KV PR versus stock, reverse-order pass); reported difference: engine build
    Second pass at reported 32768-token depth; warm-up discarded
  • 51.81 tok/s — generation speed (per request) · API server · 1 client
    Compared with 37.04 tok/s (split-KV PR versus stock, first pass); reported difference: engine build
    First pass at reported 1024-token depth; same checkpoint and harness
  • 51.43 tok/s — generation speed (per request) · API server · 1 client
    Compared with 37.76 tok/s (split-KV PR versus stock, reverse-order pass); reported difference: engine build
    Second pass at reported 1024-token depth; warm-up discarded

Not reported: configured context, system memory, Checkpoint digest, Exact container digest in summary, Native Windows applicability, Multi-client behavior, Broader task quality

  • The tested split-KV PR is unmerged and not a stock vLLM feature.
  • Linux VFIO test is not a native Windows deployment result.
  • An intermediate depth had two distinct performance modes and is not represented as one stable value.
  • Related cadamcat rows are the same host and author, not independent replication.

Setup guide (external)

Related link (external)

Known gaps (as researched)

  • No controlled, completed native-Windows Qwen3.8-27B throughput comparison was verified for dual RX 7900 XT at matched context and concurrent load. A reported stream stall is not a measured result.

Discussion

Share setups, questions and your own results. Posts are reviewed before they appear. Replies from Bitworks staff are marked.

Log in Create an account to join the discussion.

Bitworks listings for this card

Select the fields to be shown. Others will be hidden. Drag and drop to rearrange the order.
  • Image
  • SKU
  • Rating
  • Price
  • Stock
  • Availability
  • Add to cart
  • Description
  • Content
  • Weight
  • Dimensions
  • Additional information
Click outside to hide the comparison bar
Compare
Compare ×
Let's Compare! Continue shopping