Qwen3.8-27B UD-IQ4_XS on the Radeon RX 7900 XT 20GB (Windows)
Candidate
Vulkan engine option for the RX 7900 XT 20GB on Windows, measured by Bitworks with llama.cpp b10698 (Vulkan), built into FastLLM.
What will be tested
| Card | 1 × AMD Radeon RX 7900 XT 20GB |
|---|---|
| Operating system | Windows |
| Backend | Vulkan |
| Model | Qwen3.8-27B (Apache-2.0) |
| Model file | Unsloth GGUF conversion, UD-IQ4_XS |
| Context | 16,384 tokens |
| Concurrent requests | 1 (one request at a time) |
| Placement | Full GPU |
| Reviewed | Not yet |
| Sources | Upstream model · GGUF file page |
What to expect
No qualified Bitworks benchmark is published for this recipe. A lab observation is shown below.
Bitworks lab observation (not fully qualified)
Measured by Bitworks on our lab bench with the published methodology. Not fully qualified: residency, peak VRAM, soak and reference-quality gates are not all proven for this run.
FastLLM recipe: rx-7900-xt.qwen3.8-27b-ud-iq4-xs.16k
Included in FastLLM Preview 2026.10.21.12 as this card’s fallback setup: FastLLM uses it if the HIP components are not installed or their license is declined.
- Engine: llama.cpp b10698
- Backend: Vulkan
- Context: 16,384 tokens
- KV cache: f16/f16
- Slots: 1
- BAR workaround: off (ReBAR on)
| Prompt tokens | Prompt processing (tok/s) | Generation (tok/s) | Time to first text (ms) |
|---|---|---|---|
| 512 | 517.0 (493.4–519.6) | 32.5 (31.3–33.3) | 1,040 (989–1,261) |
| 4,096 | 589.6 (586.1–591.0) | 31.5 (31.1–31.9) | 6,949 (6,933–6,991) |
FastLLM self-test on this bench
Result: Passed
33.9 tok/s generation · 532.1 tok/s prompt · 964 ms to first text — 512-token prompt, 2 measured runs after 1 warm-up, server timings
FastLLM runs this quick check before it reports a setup ready. It is a short check, not the benchmark above, so the numbers are not directly comparable.
Resizable BAR on this bench
Resizable BAR (Smart Access Memory) is on. No workaround was needed.
Earlier observation (1)
Bitworks lab observation (not fully qualified)
Measured by Bitworks on our lab bench with the published methodology. Not fully qualified: residency, peak VRAM, soak and reference-quality gates are not all proven for this run.
FastLLM recipe: rx-7900-xt.qwen3.8-27b-ud-iq4-xs.16k
Included in FastLLM Preview 2026.10.21.12 as this card’s fallback setup: FastLLM uses it if the HIP components are not installed or their license is declined.
- Engine: llama.cpp b10698
- Backend: Vulkan
- Context: 16,384 tokens
- KV cache: f16/f16
- Slots: 1
- BAR workaround: off (ReBAR on)
| Prompt tokens | Prompt processing (tok/s) | Generation (tok/s) | Time to first text (ms) |
|---|---|---|---|
| 512 | 507.0 (501.8–511.2) | 32.7 (32.0–33.2) | 1,012 (1,004–1,338) |
| 4,096 | 590.4 (585.1–592.7) | 31.8 (31.6–32.9) | 6,940 (6,919–7,002) |
Download FastLLM Preview 2026.10.21.12
FastLLM Preview 2026.10.21.12 is a signed Windows release for AMD Radeon graphics (a full release on GitHub, not a pre-release). It currently sets up the AMD Radeon RX 7900 XT 20GB. It is not a qualified release, and its recipes remain candidates.
Overview
This is the Vulkan variant for the Radeon RX 7900 XT 20GB on Windows. It uses the pinned Qwen3.8-27B UD-IQ4_XS weights from Unsloth (a third-party GGUF conversion of the Qwen upstream weights), at the context size and concurrency listed on this page. The engine is llama.cpp b10698 using Vulkan, built into FastLLM.
Bitworks has measured this setup on the Radeon RX 7900 XT 20GB with that engine. The measured results, and the Resizable BAR workaround, are described with the observation on this page. It is a lab observation, not a qualification, and the recipe itself stays a candidate.
Requirements
Use a standard-user 64-bit Windows 11 system with an AMD driver exposing Vulkan and the Microsoft Visual C++ x64 runtime. Driver installation is separate from FastLLM. Check the card's currently reported free GPU memory, not just the number printed on its box. A longer prompt, more active requests and the desktop can change the memory budget.
The pinned GGUF is 14,252,845,984 bytes (14.25 GB decimal). Keep more free local SSD space than the artifact itself for verified acquisition and cache maintenance. Review the exact model license before acquisition.
Limitations
- Measured by Bitworks on this card with llama.cpp b10698 (Vulkan), built into FastLLM. The observation shown on this page is a lab observation, not a qualification of this setup.
- AMD driver and Microsoft Visual C++ runtime setup remain separate from FastLLM; no consumer installer is released.
- This setup requests full-GPU placement; that is not a verified physical-residency or all-operations-on-GPU claim.
Bitworks listings for this card
-
In stock
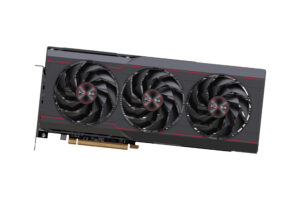 Sapphire
 PULSE AMD Radeon RX 7900 XT 20GB GDDR6 Gaming Graphics Card
$679.99 Manufacturer refurbished