Estimate — sign in for exact rates.

 Trusted GPU & AI infrastructure since 2015 — Huntsville, AL
Linux

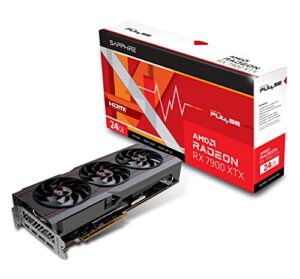
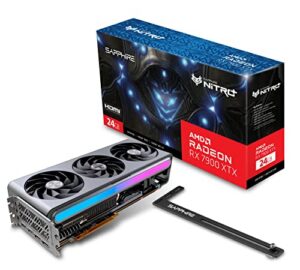
Qwen3.8-27B Q8_0 on two Radeon RX 7900 XTX 24GB cards (Linux)

Candidate

Candidate Linux dual-split configuration for RX 7900 XTX 24 GB; no published fit or performance result.

What will be tested

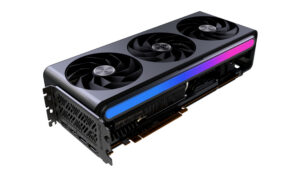
Card2 × AMD Radeon RX 7900 XTX 24GB, one model split across both cards
Operating systemLinux
BackendNot yet selected
ModelQwen3.8-27B (Apache-2.0)
Model fileUnsloth GGUF conversion, Q8_0
Context16,384 tokens
Concurrent requests1 (one request at a time)
PlacementFull GPU
ReviewedNot yet
Sources Upstream model · GGUF file page

Other goals for this card and OS: balanced goal

What to expect

No published results yet. Measured results appear here only after testing and review.

Community reports — not measured or reproduced by Bitworks

Reported by others, linked to the original. Bitworks has not verified these numbers; they can differ on your system.

Reported on Reddit by ghosthand Original report

Not reproduced by Bitworks

Qwen3.8-27B on dual RX 7900 XTX with tensor split and MTP

Method (as reported): Author compared single-GPU non-MTP and dual-tensor MTP server rows with f16 KV and flash attention.

  • Reported GPU setup RX 7900 XTX
  • GPU count 2
  • Operating system Linux (Docker ROCm)
  • Environment Container
  • Engine llama.cpp server-rocm b10481 (25ae3a9b3)
  • Backend ROCm
  • Model Qwen3.8-27B UD-IQ4_XS
  • Configured context 131,072 tokens
  • Actual input 86,675 tokens
  • Full window tested no
  • Reported context Author also configured 262144; not the occupied depth in these rows.
  • Simultaneous clients 1
  • Workers 1
  • Topology dual-split (tensor split; PCIe 4.0 x16 CPU plus x4 chipset)
  • Speculative decoding MTP
  • CPU Ryzen 9 9950X
  • Memory configuration 96 GB reported; unit not verified
  • PCIe PCIe 4.0 x16 CPU plus x4 chipset
  • 69.25 tok/s — generation speed (per request) · API server · 1 client · input 86,675 tokens
    Compared with 29.28 tok/s (baseline single GPU/no MTP; reported dual tensor/MTP); changed between the two runs: GPU count, split mode, speculative decoding, context
    Same reported prompt; f16 KV, flash attention; baseline also changed context.
    This row: configured context: 131,072 tokens · speculative decoding: MTP · topology: dual-split · cards: 2
  • 361 tok/s — prompt speed (per request) · API server · 1 client · input 86,675 tokens
    Compared with 516 tok/s (single GPU without MTP vs dual tensor with MTP); changed between the two runs: GPU count, split mode, speculative decoding, context
    Same reported prompt; f16 KV, flash attention; baseline also changed context.
    This row: configured context: 131,072 tokens · speculative decoding: MTP · topology: dual-split · cards: 2

Not reported: system memory, artifact digest, sample count and variance, physical memory residency

  • UD-IQ4_XS differs from the linked Q8_0 recipe.
  • The comparison changes GPU count, split mode, MTP, and configured context; it does not isolate a speedup cause.
  • The larger configured window was not filled by the prompt.

Related reports from the same author or project — not independent replication

Reported on Reddit by nasone32 Original report

Not reproduced by Bitworks

Dual RX 7900 XTX tensor parallel on limited PCIe

Method (as reported): Author used rocprofv3 on a saturated chipset link and combined transfer compression with a larger patch set.

HEAD seen at retrieval: 15995a12d1d5 (not necessarily the commit the author measured)

  • Reported GPU setup RX 7900 XTX
  • GPU count 2
  • Operating system Linux (Ubuntu 24; ROCm 7.14)
  • Engine custom llama.cpp HIP fork
  • Backend ROCm
  • Model Qwen3.8-27B Q8_0
  • Actual input input length not reported
  • Reported context Prompt row has known input length; decode range may use another condition.
  • Workers 1
  • Topology dual-split (tensor split; one chipset-connected PCIe x4 card)
  • Speculative decoding adaptive MTP in decode range
  • PCIe one chipset-connected PCIe x4 card
  • ≈1400 tok/s — prompt speed (per request) · input 8,192 tokens
    Compared with 1100 tok/s (baseline patched AllReduce; reported Q8 transfer); changed between the two runs: engine build, other
    Approximate author comparison on the same asymmetric host.
    This row: topology: dual-split
  • ≈60–65 tok/s — generation speed (per request)
    Combined RDNA Boost and adaptive MTP patch set; not isolated transfer-only data.
    This row: speculative decoding: adaptive MTP · topology: dual-split

Not reported: configured context, simultaneous clients, CPU, system memory, exact tested fork commit, artifact digest, replications, quality delta, full launch arguments

  • Custom patch set differs from the linked recipe and is not a stock Windows path.
  • Same author and host as the topology report; not an independent replication.
  • Author had not evaluated quality impact of Q8 inter-card transfer.
  • Fork author says combined build will not be maintained.

Setup guide (external)

Related link (external)

Reported on Reddit by nasone32 Original report

Not reproduced by Bitworks

Notes on dual RX 7900 XTX tensor split topology

Method (as reported): Author compared layer and patched tensor split on an asymmetric dual-card host; exact test counts not supplied.

  • Reported GPU setup RX 7900 XTX
  • GPU count 2
  • Operating system Linux (ROCm Linux; Windows failure also described)
  • Engine custom llama.cpp HIP
  • Backend ROCm
  • Model Qwen3.8-27B Q8_0
  • Actual input input length not reported
  • Workers 1
  • Topology dual-split (PCIe 4.0 x16 CPU plus x4 chipset)
  • Speculative decoding MTP3 in generation comparison
  • PCIe PCIe 4.0 x16 CPU plus x4 chipset
  • ≈1150 tok/s — prompt speed (per request)
    Compared with 1500 tok/s (baseline layer split; reported patched tensor split); changed between the two runs: split mode, engine build
    Approximate author-reported comparison on asymmetric PCIe topology.
    This row: topology: dual-split
  • ≈50 tok/s — generation speed (per request)
    Compared with 30 tok/s (baseline layer split; reported patched tensor/MTP3); changed between the two runs: split mode, engine build, speculative decoding
    Approximate prose comparison; split and speculation both changed.
    This row: speculative decoding: MTP3 · topology: dual-split

Not reported: configured context, actual input length, simultaneous clients, CPU, system memory, exact build and patch digest, prompt and output counts, repetition and variance, Windows version and driver

  • Custom internal AllReduce runtime differs from the linked recipe.
  • The generation comparison changes both split and MTP settings.
  • Author-reported Windows P2P failure does not establish a native-Windows tensor recipe.
  • Predicted symmetric-slot gains are not measurements.

Install

Candidate — no installer yet.

Overview

This Linux candidate proposes splitting one pinned Qwen3.8-27B Q8_0 model across two RX 7900 XTX 24 GB cards with a layer split, one active request and 16,384 context. Each card would hold a portion of the model; the result is not two independent answer workers. A split could make the Q8 artifact worth testing where one card cannot meet its estimated free-memory requirement, but transfers between cards may offset any capacity benefit. Neither aggregate advertised VRAM nor a requested full-layer count proves fit, residency or faster generation.

The 16K context comes from this exact Q8 catalog profile and its conservative reserve estimate. Some single-card Q4/Q6 profiles specify 32K, but that does not establish that this Q8 pair is limited to 16K or that the longer single-card setting would fit here. Compare matched contexts when testing latency or throughput.

Requirements

The current private Linux guided launcher accepts one Vulkan GPU, so this two-card configuration is a proposed extension, not a runnable FastLLM recipe today. A future launcher must bind both devices and verify the exact model and consent before serving. Before attempting two cards, verify the motherboard has two usable slots and record the PCIe lanes and link speed each card actually negotiates. Check the complete system's power-supply connections/capacity and case airflow against both boards; no generic PSU minimum is established here. Identify both cards individually, leave memory reserves on each, and measure sustained thermals. A pair's advertised VRAM is not one contiguous pool.

The pinned GGUF is 29,047,086,048 bytes (29.05 GB decimal). Keep more free local SSD space than the artifact itself for verified acquisition and cache maintenance; no fixed extra margin or host-RAM minimum has been qualified. Review the exact model license before acquisition. A trial must record the exact device pair and topology, each card's current free VRAM, the requested split, per-card model and compute buffers, host-memory use, API output and repeated response times. Splitting capacity and two separate replicas answer different buyer needs.

Separate Flash-Next research

Qwen3.8-Flash-Next is a different model under separate Qwen Community 1.0 terms, not this pinned 27B artifact. Every full-model conversion surveyed so far has more weight data than this pair's combined GPU memory, so Flash-Next here would depend on host-memory offload. It remains research, not a recipe. Strata's AMD HIP documentation describes Linux AMD multi-card layer splitting and host expert caching but one AMD card per model on Windows. A separate exact artifact, runtime, RAM/SSD and output-quality review is needed before any FastLLM recipe.

Limitations

  • The requested layer split and full-GPU placement have no qualified two-card load, buffer, correctness or speed result.
  • The current Linux guided launcher is single-GPU; a two-card FastLLM runner is not implemented.
  • The Q8 16K context is the catalog candidate, not a measured maximum.
Select the fields to be shown. Others will be hidden. Drag and drop to rearrange the order.
  • Image
  • SKU
  • Rating
  • Price
  • Stock
  • Availability
  • Add to cart
  • Description
  • Content
  • Weight
  • Dimensions
  • Additional information
Click outside to hide the comparison bar
Compare
Compare ×
Let's Compare! Continue shopping