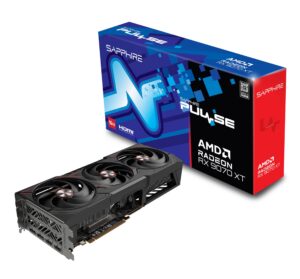
The RX 9070 XT also advertises 16 GB of GDDR6 memory, but it is not interchangeable with the non-XT RX 9070 or the RDNA 3 RX 7800 XT. The same pinned Qwen3.5-9B Q8 candidate across those pages gives a way to isolate hardware differences in later matched tests, provided driver, prompts, context and active requests are recorded.
This candidate’s 32K context and full-GPU placement are requested settings, not observed fit. Check current free memory and sustained behavior, not only a successful file download or model-load message. Windows and Linux require their own evidence, and no card-specific result is published here.
Reported by the community and linked to each original. Results can differ on your system.
Related reports from the same author or project — not independent replication
IQ4_S256 · 1 card · Linux · rainference HIP · 759 tok/s prompt (aggregate) · by rainroar on Blog
Reported on Blog by rainroar — posted 2026-09-12 · measured 2026-09-11 Original report
RX 9070 XT rainference C4 Qwen3.8-27B — DFlash2
Method (as reported): One recorded C4 SSE burst after a different-prompt warmup; cold prefill/no KV reuse; server restarted between warmup and recorded burst.
Reported GPU setup RX 9070 XT 16GB (gfx1201)
GPU count 1
Operating system Linux (Arch Linux; ROCm 7.2.4)
Engine rainference working tree; manifests 054/055 applied
Backend HIP
Model Qwen3.8-27B IQ4_S256
Configured context 16,384 tokens
Actual input 3,400 tokens
Output 512 tokens
Full window tested no
Reported context Shared 16K paged pool; four slots labelled 4K; 3,400+512 tokens per request.
Simultaneous clients 4
Server slots 4
Workers 1
Topology single (One RX 9070 XT; engine compiled for a maximum of four sequences.)
Offload other (Input embedding on host (--emb-host); other placement unreported.)
CPU Ryzen 9 9900X
Memory configuration 60 GB RAM as reported; byte convention unknown
Host notes Desktop compositor shared the GPU during the reported run.
98.3 tok/s — other (aggregate across clients) · API server · 4 clients · input 3,400 tokens Steady window: 1,947 output tokens over 19.8 s, from last stream's first token to burst end; no prefill outstanding.
81.6 tok/s — other (aggregate across clients) · API server · 4 clients · input 3,400 tokens Decode-phase aggregate begins at each stream's first token and includes overlap with unfinished prompt processing.
54.3 tok/s — other (aggregate across clients) · API server · 4 clients · input 3,400 tokens Full-burst aggregate uses all 2,048 generated tokens and includes four cold prompt-processing phases.
24.6 tok/s — other (per request) · API server · 4 clients · input 3,400 tokens Author-reported per-stream rate for the C4 burst; not a latency percentile.
759 tok/s — prompt speed (aggregate across clients) · API server · 4 clients · input 3,400 tokens Aggregate cold prefill across four distinct-prefix prompts; 256-token server-side chunks and no KV reuse.
4.2–17.92 s — time to first token (per request) · API server · 4 clients · input 3,400 tokens First-to-last stream TTFT range after simultaneous release; not a percentile.
15.91 GB — memory used (server-wide) · API server · 4 clients · input 3,400 tokens Peak VRAM from the author's periodic sampler on the single card.
Not reported: model file checksum, system memory, Public rainference repository, source commit and license, GPU driver version, Main and draft artifact digests and download provenance, Repeated samples, variance and run-order effects, Raw prompt/output bundles behind author-reported digests, Output grading, cancellation and sustained stability, Remaining model and operation placement
One self-published author and host; no statistical winner follows from the three arms.
Linux custom rainference/HIP evidence only; it does not establish native-Windows or FastLLM behavior.
The custom .raif artifacts are not FastLLM catalog GGUFs; engine source, build, license and artifact digests are unverified.
Input embeddings are on the host; remaining model and operation placement and dedicated-memory residency are not proven.
The engine was compiled for at most four sequences; this is no evidence for C8 behavior.
Method (as reported): C4 SSE comparison burst under the same stated workload; cold prefill/no KV reuse; server restart required; repetition count unreported.
Reported GPU setup RX 9070 XT 16GB (gfx1201)
GPU count 1
Operating system Linux (Arch Linux; ROCm 7.2.4)
Engine rainference working tree; manifests 054/055 applied
Backend HIP
Model Qwen3.8-27B IQ4_S256
Configured context 16,384 tokens
Actual input 3,400 tokens
Output 512 tokens
Full window tested no
Reported context Shared 16K paged pool; four slots labelled 4K; 3,400+512 tokens per request.
Simultaneous clients 4
Server slots 4
Workers 1
Topology single (One RX 9070 XT; engine compiled for a maximum of four sequences.)
Speculative decoding in-file MTP head
Offload other (Input embedding on host (--emb-host); other placement unreported.)
CPU Ryzen 9 9900X
Memory configuration 60 GB RAM as reported; byte convention unknown
Host notes Desktop compositor shared the GPU during the reported run.
96 tok/s — other (aggregate across clients) · API server · 4 clients · input 3,400 tokens Steady window starts at the last stream's first token and ends at burst completion; no prefill outstanding.
83 tok/s — other (aggregate across clients) · API server · 4 clients · input 3,400 tokens Decode-phase aggregate begins at each stream's first token and includes overlap with unfinished prompt processing.
56.1 tok/s — other (aggregate across clients) · API server · 4 clients · input 3,400 tokens Full-burst aggregate uses all 2,048 generated tokens and includes four cold prompt-processing phases.
24 tok/s — other (per request) · API server · 4 clients · input 3,400 tokens Author-reported per-stream rate for the C4 burst; not a latency percentile.
835 tok/s — prompt speed (aggregate across clients) · API server · 4 clients · input 3,400 tokens Aggregate cold prefill across four distinct-prefix prompts; 256-token server-side chunks and no KV reuse.
3.8–16.29 s — time to first token (per request) · API server · 4 clients · input 3,400 tokens First-to-last stream TTFT range after simultaneous release; not a percentile.
15.02 GB — memory used (server-wide) · API server · 4 clients · input 3,400 tokens Peak VRAM from the author's periodic sampler on the single card.
Not reported: system memory, Public rainference repository, source commit and license, GPU driver version, Main artifact digest and download provenance, Repeated samples, variance and run-order effects, Raw prompt/output bundles behind author-reported digests, Output grading, cancellation and sustained stability, Remaining model and operation placement
One self-published author and host; no statistical winner follows from the three arms.
Linux custom rainference/HIP evidence only; it does not establish native-Windows or FastLLM behavior.
The custom .raif artifact is not a FastLLM catalog GGUF; engine source, build, license and artifact digest are unverified.
Input embeddings are on the host; remaining model and operation placement and dedicated-memory residency are not proven.
The engine was compiled for at most four sequences; this is no evidence for C8 behavior.
IQ4_S256 · 1 card · Linux · rainference HIP · 871 tok/s prompt (aggregate) · by rainroar on Blog
Reported on Blog by rainroar — posted 2026-09-12 · measured 2026-09-11 Original report
RX 9070 XT rainference C4 Qwen3.8-27B — no speculation
Method (as reported): C4 SSE comparison burst under the same stated workload; cold prefill/no KV reuse; server restart required; repetition count unreported.
Reported GPU setup RX 9070 XT 16GB (gfx1201)
GPU count 1
Operating system Linux (Arch Linux; ROCm 7.2.4)
Engine rainference working tree; manifests 054/055 applied
Backend HIP
Model Qwen3.8-27B IQ4_S256
Configured context 16,384 tokens
Actual input 3,400 tokens
Output 512 tokens
Full window tested no
Reported context Shared 16K paged pool; four slots labelled 4K; 3,400+512 tokens per request.
Simultaneous clients 4
Server slots 4
Workers 1
Topology single (One RX 9070 XT; engine compiled for a maximum of four sequences.)
Speculative decoding none
Offload other (Input embedding on host (--emb-host); other placement unreported.)
CPU Ryzen 9 9900X
Memory configuration 60 GB RAM as reported; byte convention unknown
Host notes Desktop compositor shared the GPU during the reported run.
98.2 tok/s — other (aggregate across clients) · API server · 4 clients · input 3,400 tokens Steady window starts at the last stream's first token and ends at burst completion; no prefill outstanding.
83.2 tok/s — other (aggregate across clients) · API server · 4 clients · input 3,400 tokens Decode-phase aggregate begins at each stream's first token and includes overlap with unfinished prompt processing.
57.6 tok/s — other (aggregate across clients) · API server · 4 clients · input 3,400 tokens Full-burst aggregate uses all 2,048 generated tokens and includes four cold prompt-processing phases.
24.6 tok/s — other (per request) · API server · 4 clients · input 3,400 tokens Author-reported per-stream rate for the C4 burst; not a latency percentile.
871 tok/s — prompt speed (aggregate across clients) · API server · 4 clients · input 3,400 tokens Aggregate cold prefill across four distinct-prefix prompts; 256-token server-side chunks and no KV reuse.
3.72–15.61 s — time to first token (per request) · API server · 4 clients · input 3,400 tokens First-to-last stream TTFT range after simultaneous release; not a percentile.
14.26 GB — memory used (server-wide) · API server · 4 clients · input 3,400 tokens Peak VRAM from the author's periodic sampler on the single card.
Not reported: system memory, Public rainference repository, source commit and license, GPU driver version, Main artifact digest and download provenance, Repeated samples, variance and run-order effects, Raw prompt/output bundles behind author-reported digests, Output grading, cancellation and sustained stability, Remaining model and operation placement
One self-published author and host; no statistical winner follows from the three arms.
Linux custom rainference/HIP evidence only; it does not establish native-Windows or FastLLM behavior.
The custom .raif artifact is not a FastLLM catalog GGUF; engine source, build, license and artifact digest are unverified.
Input embeddings are on the host; remaining model and operation placement and dedicated-memory residency are not proven.
The engine was compiled for at most four sequences; this is no evidence for C8 behavior.
Q4_K_M and AD-IQ4_XS-IQ3_S (separate arms) · 1 card · Windows · llama.cpp ROCm/HIP · 24 tok/s (other measure, see details) · 42 tok/s (other measure, see details) · by Ataa Aldaghstani / ataadevs on Blog
Reported on Blog by Ataa Aldaghstani / ataadevs — posted 2026-08-17 Original report
RX 9070 XT Windows Qwen3.8 coding-task MTP comparison
Method (as reported): Same repository-explanation task; q4_0 K/V, FA on, fit off; author averages with timing denominator unspecified.
Reported GPU setup RX 9070 XT 16GB
GPU count 1
Operating system Windows (Windows)
Engine llama.cpp
Backend ROCm/HIP
Model Qwen3.8-27B Q4_K_M and AD-IQ4_XS-IQ3_S (separate arms)
24 tok/s — other (scope not stated) · agent session · 1 client Compared with 17 tok/s (Q4_K_M no MTP vs MTP2); reported difference: speculative decoding Author average; timing denominator unspecified; Q4_K_M at configured 32,096; repository-explanation task. This row: configured context: 32,096 tokens · quantisation: Unsloth Q4_K_M · speculative decoding: MTP2
42 tok/s — other (scope not stated) · agent session · 1 client Compared with 27.5 tok/s (AtomicChat mixed quant no MTP vs MTP2); reported difference: speculative decoding Author average; timing denominator unspecified; mixed quant at configured 64,096; repository-explanation task. This row: configured context: 64,096 tokens · quantisation: AtomicChat AD-IQ4_XS-IQ3_S · speculative decoding: MTP2
Not reported: model file checksum, system memory, Artifact/build digests, Occupied inputs and output counts, Timing denominator, Repetitions/variance, Objective task scoring
Q4 arms required mid-task compaction.
Mixed-quant MTP quality was judged weaker subjectively.
43.75 tok/s — generation speed (per request) · API server · 1 client · input 32,996 tokens Compared with 25.74 tok/s (Same custom fork no MTP vs MTP n3); reported difference: speculative decoding Single cold L2 Windows HIP cell; 32,996 input / 256 output; custom fork and uncommitted FA change. This row: configured context: 49,152 tokens · speculative decoding: MTP n3
1799.29 tok/s — prompt speed (per request) · API server · 1 client · input 32,996 tokens Compared with 1879.06 tok/s (Same custom fork no MTP vs MTP n3); reported difference: speculative decoding Same one-run L2 Windows HIP comparison; reported prompt processing declined. This row: configured context: 49,152 tokens · speculative decoding: MTP n3
Not reported: model file checksum, Exact executable/artifact hashes, Uncommitted change identity, Windows raw receipts unavailable in pinned tree, Repeated-run variance, Concurrent throughput
Specialized fork, not stock FastLLM.
Do not infer dual-card scaling without a single-card control.
Windows/Linux comparisons also change driver and P2P.
W24/W26 kernel gains belong to separate Linux research lanes.
IQ4_XS-v3 · 1 card · Linux · llama.cpp HIP ROCm · 28.41 tok/s generation · 1193 tok/s prompt · by kr4ckhe4d on GitHub
Reported on GitHub by kr4ckhe4d · measured 2026-10-02 Original report
Qwen3.8 llama.cpp build comparison on RX 9070 XT
Method (as reported): ABBA build order; two server loads per build, two deep measures/load plus discarded warmup; Q8 KV, batch 2048, microbatch 1024, FA on.
HEAD seen at retrieval: c18f1bc96ce3 (not necessarily the commit the author measured)
Discussion
Share setups, questions and your own results. Posts are reviewed before they appear. Replies from Bitworks staff are marked.