Estimate — sign in for exact rates.

 Trusted GPU & AI infrastructure since 2015 — Huntsville, AL
16 GB GDDR6 · RDNA 4 · gfx1201

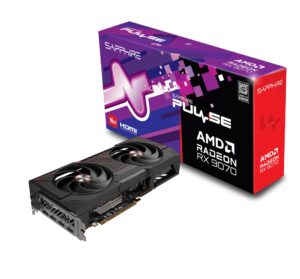
AMD Radeon RX 9070 16GB

What this card can do

One card
9B models at 8-bit, 32K context
Windows
Windows preview, lab-measured
Linux
Linux lab alpha, unqualified

The RX 9070 has 16 GB of GDDR6 memory and is distinct from the RX 9070 XT. Its candidate Qwen3.5-9B Q8 profile can later be compared against other 16 GB cards using the same exact model file and prompts. Shared capacity alone does not establish matching clocks, thermals or response behavior.

For a meaningful test, note the driver and runtime, actual free GPU memory, desktop load and completed-output timing. A 32K catalog context is requested, not qualified. The Windows Vulkan path and private Linux path need separate card evidence; neither can borrow a result from another Radeon variant.

AMD specifications

Models on this card

Qwen3.5-9B Model page

Bitworks

Bitworks measurements: none published yet.

Community

Reported by the community and linked to each original. Results can differ on your system.

UD-Q6_K_XL · 1 card · Linux · llama.cpp HIP/ROCm 7.x · 32 tok/s generation · by shawnq-msft on GitHub

Reported on GitHub by shawnq-msft Original report

RX 9070 WSL ROCm Qwen field notes

Method (as reported): Author-maintained serving presets and evaluations; repetitions for this decode row not stated.

HEAD seen at retrieval: ff5a20a8fddc (not necessarily the commit the author measured)

  • Reported GPU setup RX 9070 non-XT 16GB
  • GPU count 1
  • Operating system Linux (WSL2 Linux guest on Windows host)
  • Environment WSL2 guest on Windows
  • Engine llama.cpp
  • Backend HIP/ROCm 7.x
  • Model Qwen3.5-9B UD-Q6_K_XL
  • Configured context 16,000 tokens
  • Actual input input length not reported
  • Reported context Configured context reported; actual occupied prompt not stated.
  • Simultaneous clients 1
  • Workers 1
  • Topology single
  • 32 tok/s — generation speed (per request) · 1 client
    Author's single-stream q8_0 KV field-note profile

Reported quality

  • 0.7073 fraction — reported quality score (scope not stated) · 1 client
    HumanEval pass@1, 164 tasks; author-reported Q6_K_XL profile
    This row: configured context: 16,000 tokens

Not reported: CPU, system memory, Exact engine revision, GGUF digest, Actual occupied prompt, Sample variance, Native Windows result

  • WSL2 is not native Windows serving.
  • The author's Q4_K_XL and Qwopus results concern different artifacts and are not combined here.
  • HumanEval is an author-reported small-model evaluation, not a Bitworks quality endorsement.
  • Snapshot commit is the retrieved report revision, not the measured engine revision.

Setup guide (external)

Qwen3.8-27B Model page

Bitworks

Bitworks: no recipe for this card yet.

Community

IQ3-MIX · 1 card · Windows · llama.cpp ROCm 7.14 HIP · 23.1 tok/s generation · 335 tok/s prompt · by ExpensiveParfait677 on Reddit

Reported on Reddit by ExpensiveParfait677 Original report

RX 9070 non-XT Windows Qwen3.8 agent and context report

Method (as reported): One-slot llama-server with FA, q4 K/V and MTP2; on-box long-prompt and agent harness observations.

  • Reported GPU setup RX 9070 non-XT 16GB
  • GPU count 1
  • Operating system Windows (Windows 11)
  • Engine llama.cpp b10587, Clang 20.1.8
  • Backend ROCm 7.14 HIP
  • Model Qwen3.8-27B IQ3-MIX (vmarcelo)
  • Configured context 131,072 tokens
  • Actual input input length not reported
  • Reported context On-box test used about 83K occupied prompt tokens.
  • Simultaneous clients 1
  • Server slots 1
  • Workers 1
  • Topology single
  • Speculative decoding MTP2 plus ngram-mod
  • CPU Ryzen 7 7800X3D
  • Memory configuration 32 GB RAM
  • 23.1 tok/s — generation speed (per request) · API server · 1 client
    On-box approximately 83K occupied prompt; q4_0 K/V, MTP2
    This row: configured context: 131,072 tokens
  • 335 tok/s — prompt speed (per request) · API server · 1 client
    Same approximately 83K occupied prompt
    This row: configured context: 131,072 tokens
  • ≈3.3 s — time to first token (per request) · agent session · 1 client
    Approximate continuation TTFT in agent harness use
    This row: configured context: 131,072 tokens
  • 5.4 tok/s — generation speed (per request) · API server · 1 client
    Q8_0 K/V exceeded dedicated VRAM; WDDM shared-memory spill
    This row: configured context: 131,072 tokens

Not reported: system memory, Exact GGUF digest, Successful HIP driver version, Repeated samples and variance, Physical WDDM residency, Concurrent-client rate

  • IQ3-MIX differs from FastLLM catalog artifacts.
  • Reported VRAM values are not independent proof of dedicated residency.
  • Q8 KV spilled to shared memory in the author's setup.
  • The small quality spot-check does not establish broad model quality.
Setup guide (external)

Qwen3.8-Flash-Next

Bitworks

Bitworks: no recipe for this card yet.

References

Discussion

Share setups, questions and your own results. Posts are reviewed before they appear. Replies from Bitworks staff are marked.

Log in Create an account to join the discussion.